SQL · Guides · October 30, 2026 · 12 min read
ROW_NUMBER vs RANK vs DENSE_RANK in SQL: the difference on ties
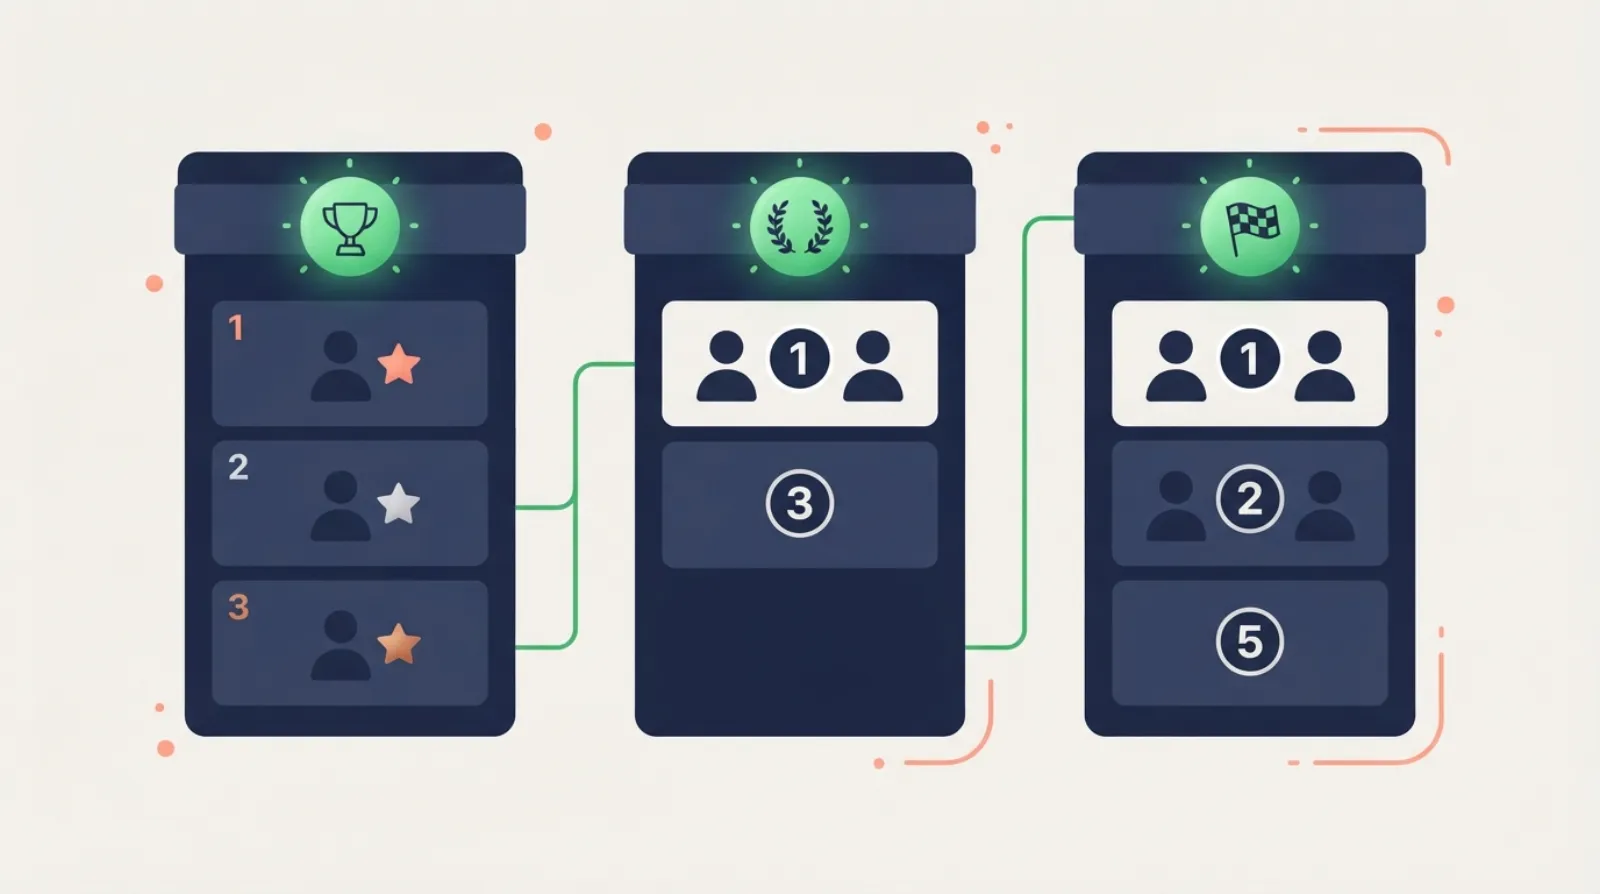
ROW_NUMBER(), RANK() and DENSE_RANK() all number rows in the order you give in OVER (ORDER BY ...). They give the same result until two rows tie. On a tie, ROW_NUMBER still hands out unique numbers (1, 2, 3, 4), RANK gives tied rows the same number and then skips (1, 2, 2, 4), and DENSE_RANK gives tied rows the same number without skipping (1, 2, 2, 3). In practice: ROW_NUMBER for “exactly N rows” and deduplication, RANK for leaderboards where ties share a place, DENSE_RANK for “the Nth highest value”.
All examples run on the airline database from the Nomto SQL course, in PostgreSQL syntax on DuckDB (the engine of the Nomto SQL room), and every result table is the real output. For the wider picture of OVER, frames, running totals and LAG, see the SQL window functions guide; this page is only about the ranking functions.
The difference in one table
A leaderboard of loyalty members by the number of flight segments they flew. Several members have the same count, which is exactly where the three functions part ways:
WITH m AS (
  SELECT tm.member_id, COUNT(*) AS flights
  FROM ticket_members tm
  JOIN ticket_flights tf ON tf.ticket_no = tm.ticket_no
  GROUP BY tm.member_id
)
SELECT member_id, flights,
       ROW_NUMBER() OVER (ORDER BY flights DESC, member_id) AS row_num,
       RANK()       OVER (ORDER BY flights DESC) AS rnk,
       DENSE_RANK() OVER (ORDER BY flights DESC) AS dense_rnk
FROM m
ORDER BY row_num
LIMIT 11;| member_id | flights | row_num | rnk | dense_rnk |
|---|---|---|---|---|
| 12589 | 33 | 1 | 1 | 1 |
| 2969 | 32 | 2 | 2 | 2 |
| 1659 | 31 | 3 | 3 | 3 |
| 8943 | 31 | 4 | 3 | 3 |
| 37704 | 31 | 5 | 3 | 3 |
| 39173 | 31 | 6 | 3 | 3 |
| 9128 | 30 | 7 | 7 | 4 |
| 15845 | 30 | 8 | 7 | 4 |
| 35285 | 30 | 9 | 7 | 4 |
| 38397 | 30 | 10 | 7 | 4 |
| 6702 | 29 | 11 | 11 | 5 |
Read it row by row:
- ROW_NUMBER counts 1 to 11 regardless of ties. The four members with 31 flights get 3, 4, 5 and 6 only because of the tie-breaker
member_idin itsORDER BY. - RANK gives all four the 3rd place, then jumps to 7: places 4, 5 and 6 are “used up” by the tie. It is the position “how many rows are ahead of me, plus one”.
- DENSE_RANK also gives them 3, then continues with 4. It numbers the distinct values: 33, 32, 31, 30, 29 are the 1st to 5th distinct flight counts.
The same rule in a sentence: RANK counts rows, DENSE_RANK counts distinct values, ROW_NUMBER ignores ties.
How many rows “top 5” returns with each
Because they treat ties differently, a filter like <= 5 returns a different number of rows with each function:
WITH m AS (
  SELECT tm.member_id, COUNT(*) AS flights
  FROM ticket_members tm
  JOIN ticket_flights tf ON tf.ticket_no = tm.ticket_no
  GROUP BY tm.member_id
), r AS (
  SELECT member_id, flights,
         ROW_NUMBER() OVER (ORDER BY flights DESC, member_id) AS row_num,
         RANK()       OVER (ORDER BY flights DESC) AS rnk,
         DENSE_RANK() OVER (ORDER BY flights DESC) AS dense_rnk
  FROM m
)
SELECT COUNT(*) FILTER (WHERE row_num <= 5)   AS by_row_number,
       COUNT(*) FILTER (WHERE rnk <= 5)       AS by_rank,
       COUNT(*) FILTER (WHERE dense_rnk <= 5) AS by_dense_rank
FROM r;| by_row_number | by_rank | by_dense_rank |
|---|---|---|
| 5 | 6 | 14 |
ROW_NUMBER <= 5always returns exactly 5 rows, and it silently drops one of the four members tied at 31.RANK <= 5returns 6: everyone whose place is 5 or better, so all four members tied at 3rd place are in.DENSE_RANK <= 5returns 14: everyone with one of the top five flight counts (33, 32, 31, 30 or 29).
None of them is wrong; they answer different questions. Decide which question you are asked before you pick the function.
Top N per group with PARTITION BY
Add PARTITION BY and the numbering restarts in each group. The top 3 members per home airport for two airports, with all three functions side by side:
WITH m AS (
  SELECT lm.home_airport, tm.member_id, COUNT(*) AS flights
  FROM ticket_members tm
  JOIN ticket_flights tf ON tf.ticket_no = tm.ticket_no
  JOIN loyalty_members lm ON lm.member_id = tm.member_id
  WHERE lm.home_airport IN ('VKO', 'OVB')
  GROUP BY lm.home_airport, tm.member_id
), r AS (
  SELECT home_airport, member_id, flights,
         ROW_NUMBER() OVER (PARTITION BY home_airport ORDER BY flights DESC, member_id) AS rn,
         RANK()       OVER (PARTITION BY home_airport ORDER BY flights DESC) AS rnk,
         DENSE_RANK() OVER (PARTITION BY home_airport ORDER BY flights DESC) AS dense_rnk
  FROM m
)
SELECT * FROM r
WHERE rnk <= 3
ORDER BY home_airport, rn;| home_airport | member_id | flights | rn | rnk | dense_rnk |
|---|---|---|---|---|---|
| OVB | 39502 | 28 | 1 | 1 | 1 |
| OVB | 9835 | 25 | 2 | 2 | 2 |
| OVB | 4544 | 24 | 3 | 3 | 3 |
| OVB | 27427 | 24 | 4 | 3 | 3 |
| OVB | 38226 | 24 | 5 | 3 | 3 |
| OVB | 39050 | 24 | 6 | 3 | 3 |
| VKO | 39173 | 31 | 1 | 1 | 1 |
| VKO | 6702 | 29 | 2 | 2 | 2 |
| VKO | 17160 | 29 | 3 | 2 | 2 |
| VKO | 32434 | 29 | 4 | 2 | 2 |
Filtering on rnk <= 3 returns six rows for Novosibirsk (a four-way tie for 3rd place) and four for Vnukovo (a three-way tie for 2nd). With rn <= 3 you would get exactly three per airport, and which of the tied members makes the cut would depend on the tie-breaker alone. For a prize list, that is unfair; for a “show three examples per airport” widget, it is what you want.
Two rules apply to every top-N query:
- Filter outside.
WHERE rnk <= 3cannot sit in the sameSELECTthat computesrnk, becauseWHEREruns before window functions. Compute the rank in a CTE or subquery and filter in the outer query. DuckDB, Snowflake, BigQuery and Databricks also accept aQUALIFY rnk <= 3clause; PostgreSQL, MySQL and SQL Server do not. - Partition by the group, order by the metric.
PARTITION BY home_airport ORDER BY flights DESCmeans “within each airport, by flights”. ForgettingPARTITION BYranks across the whole table.
Deduplication: keep one row per key with ROW_NUMBER
For removing duplicates, ties are the whole point: duplicate rows tie on everything, and you want to keep exactly one. That is a job for ROW_NUMBER, never RANK, which would number both copies 1 and keep both.
The app_events table receives some events twice: same client, same event, same event_time, different received_at. Number the copies, oldest arrival first:
SELECT event_id, event_name, event_time, received_at,
       ROW_NUMBER() OVER (PARTITION BY client_id, event_name, event_time
                          ORDER BY received_at, event_id) AS rn
FROM app_events
WHERE client_id = '000034d98b23' AND event_time < '2026-07-05 02:00'
ORDER BY event_time, rn;| event_id | event_name | event_time | received_at | rn |
|---|---|---|---|---|
| 131068 | app_open | 2026-07-05 01:02:07 | 2026-07-05 01:02:07 | 1 |
| 131081 | search | 2026-07-05 01:02:31 | 2026-07-05 01:02:31 | 1 |
| 131116 | search | 2026-07-05 01:02:31 | 2026-07-05 01:03:56 | 2 |
| 131085 | view_offer | 2026-07-05 01:02:41 | 2026-07-05 01:02:42 | 1 |
| 131096 | select_fare | 2026-07-05 01:03:32 | 2026-07-05 01:03:34 | 1 |
The search event arrived twice, 85 seconds apart; the copy gets rn = 2. Keep rn = 1 across the whole table:
WITH ranked AS (
  SELECT ROW_NUMBER() OVER (PARTITION BY client_id, event_name, event_time
                            ORDER BY received_at, event_id) AS rn
  FROM app_events
)
SELECT COUNT(*) AS all_rows,
       COUNT(*) FILTER (WHERE rn = 1) AS kept,
       COUNT(*) FILTER (WHERE rn > 1) AS duplicates
FROM ranked;| all_rows | kept | duplicates |
|---|---|---|
| 1494723 | 1484034 | 10689 |
The PARTITION BY columns define what “the same row” means; the ORDER BY decides which copy survives (here the first received; ORDER BY received_at DESC would keep the latest). Add a unique column such as event_id at the end so the choice is repeatable. Other ways to find and remove duplicates are compared in how to find duplicates in SQL.
Nth highest value: DENSE_RANK
“Find the second highest fare” is a classic interview question, and it is where RANK quietly fails. Many tickets share the same price:
WITH p AS (
  SELECT amount,
         RANK()       OVER (ORDER BY amount DESC) AS rnk,
         DENSE_RANK() OVER (ORDER BY amount DESC) AS dense_rnk
  FROM ticket_flights
)
SELECT amount, MIN(rnk) AS rnk, MIN(dense_rnk) AS dense_rnk, COUNT(*) AS tickets
FROM p
WHERE dense_rnk <= 4
GROUP BY amount
ORDER BY amount DESC;| amount | rnk | dense_rnk | tickets |
|---|---|---|---|
| 2033.00 | 1 | 1 | 427 |
| 2013.00 | 428 | 2 | 70 |
| 1998.00 | 498 | 3 | 691 |
| 1993.00 | 1189 | 4 | 856 |
427 tickets cost the top fare of $2,033, so RANK gives the next price, $2,013, the rank 428. A query with WHERE rnk = 2 returns zero rows; WHERE dense_rnk = 2 returns $2,013, the right answer. ROW_NUMBER() = 2 would return $2,033 again, because the second row is just another ticket at the top price.
WITH p AS (
  SELECT amount, DENSE_RANK() OVER (ORDER BY amount DESC) AS dense_rnk
  FROM ticket_flights
)
SELECT DISTINCT amount FROM p WHERE dense_rnk = 2;| amount |
|---|
| 2013.00 |
More questions in this style are collected in SQL interview questions.
Which one to use
| Task | Function | Why |
|---|---|---|
| Exactly N rows, top N per group with a fixed size | ROW_NUMBER |
Unique numbers; ties are cut by the tie-breaker |
| Deduplication, latest row per key | ROW_NUMBER |
Copies tie, and you need exactly one with rn = 1 |
| Pagination by a stable order | ROW_NUMBER |
Every row gets its own position |
| Leaderboard, competition places | RANK |
Ties share a place, the next place is skipped (1, 2, 2, 4) |
| Top N including everyone tied at the cutoff | RANK |
rnk <= N keeps all rows tied at place N |
| Nth highest or lowest value | DENSE_RANK |
Counts distinct values, no gaps |
| Top N distinct values (three highest prices) | DENSE_RANK |
dense_rnk <= 3 returns every row with one of those values |
One more rule: with ROW_NUMBER, always end the ORDER BY with a unique column. If the ordering has ties, the database may number tied rows differently on the next run, and your “top 5” or deduplicated table changes without any change in data. RANK and DENSE_RANK do not need this, because tied rows get the same number anyway.
NTILE, PERCENT_RANK and CUME_DIST
Three more ranking functions are worth knowing:
NTILE(n)splits the ordered rows intonbuckets of (almost) equal size: quartiles, deciles.PERCENT_RANK()is(rank - 1) / (rows - 1): 0 for the first row, 1 for the last.CUME_DIST()is the share of rows with a value less than or equal to the current one.
On the nine aircraft models, ordered by range:
SELECT model, range,
       NTILE(4) OVER (ORDER BY range DESC) AS quartile,
       ROUND(PERCENT_RANK() OVER (ORDER BY range), 3) AS pct_rank,
       ROUND(CUME_DIST() OVER (ORDER BY range), 3) AS cume_dist
FROM aircrafts
ORDER BY range DESC;| model | range | quartile | pct_rank | cume_dist |
|---|---|---|---|---|
| Boeing 777-300 | 11100 | 1 | 1 | 1 |
| Boeing 767-300 | 7900 | 1 | 0.875 | 0.889 |
| Airbus A319-100 | 6700 | 1 | 0.75 | 0.778 |
| Airbus A320-200 | 5700 | 2 | 0.625 | 0.667 |
| Airbus A321-200 | 5600 | 2 | 0.5 | 0.556 |
| Boeing 737-300 | 4200 | 3 | 0.375 | 0.444 |
| Sukhoi Superjet-100 | 3000 | 3 | 0.25 | 0.333 |
| Bombardier CRJ-200 | 2700 | 4 | 0.125 | 0.222 |
| Cessna 208 Caravan | 1200 | 4 | 0 | 0.111 |
Nine rows do not split evenly into four, so the first bucket gets the extra row (3, 2, 2, 2).
NTILE has the same blind spot as ROW_NUMBER: it ignores ties. Split all loyalty members into deciles by flights:
WITH m AS (
  SELECT tm.member_id, COUNT(*) AS flights
  FROM ticket_members tm
  JOIN ticket_flights tf ON tf.ticket_no = tm.ticket_no
  GROUP BY tm.member_id
), t AS (
  SELECT member_id, flights,
         NTILE(10) OVER (ORDER BY flights DESC, member_id) AS decile
  FROM m
)
SELECT decile, COUNT(*) AS members, MIN(flights) AS min_flights, MAX(flights) AS max_flights
FROM t
GROUP BY decile
ORDER BY decile;| decile | members | min_flights | max_flights |
|---|---|---|---|
| 1 | 4158 | 8 | 33 |
| 2 | 4158 | 6 | 8 |
| 3 | 4158 | 6 | 6 |
| 4 | 4158 | 4 | 6 |
| 5 | 4157 | 4 | 4 |
| 6 | 4157 | 4 | 4 |
| 7 | 4157 | 3 | 4 |
| 8 | 4157 | 2 | 3 |
| 9 | 4157 | 2 | 2 |
| 10 | 4157 | 1 | 2 |
The buckets are equal in size, but members with 8 flights land in both decile 1 and decile 2, and members with 4 flights are spread over four deciles. If “top 10%” must not split equal values, use PERCENT_RANK() <= 0.1 or CUME_DIST() instead, which give tied rows the same value.
Dialect notes
ROW_NUMBER, RANK, DENSE_RANK, NTILE, PERCENT_RANK and CUME_DIST are standard SQL and work the same way in PostgreSQL, DuckDB, SQL Server (2012 and later for the last two), Oracle, BigQuery and Snowflake. MySQL has them from version 8.0; MySQL 5.7 has no window functions at all. SQL Server requires ORDER BY inside OVER for all of them, ROW_NUMBER included; PostgreSQL and DuckDB accept ROW_NUMBER() OVER (), but the numbering is then arbitrary.
FAQ
What is the difference between ROW_NUMBER, RANK and DENSE_RANK?
They differ only on ties. ROW_NUMBER gives every row a unique number (1, 2, 3, 4). RANK gives tied rows the same number and skips the next ones (1, 2, 2, 4). DENSE_RANK gives tied rows the same number without skipping (1, 2, 2, 3).
Which should I use for top N per group?
ROW_NUMBER if each group must return exactly N rows. RANK if everyone tied at the N-th place should be included, which can return more than N rows per group. In both cases compute the number in a CTE and filter in the outer query.
Why does RANK skip numbers?
Because RANK is the number of rows ahead of the current one plus one. If four rows tie at 3rd place, the next row has six rows ahead of it, so it is 7th. DENSE_RANK counts distinct values instead, so the next row is 4th.
How do I get the second highest value in SQL?
Use DENSE_RANK() OVER (ORDER BY value DESC) and keep dense_rnk = 2. RANK can return nothing when the top value is shared by several rows, and ROW_NUMBER can return the top value again.
Is ROW_NUMBER deterministic?
Only if the ORDER BY inside OVER is unique. With ties in the ordering, the database may number tied rows differently between runs. Add a unique column, such as an id, as the last sort key.
Also in Español, Português (Brasil), Tiếng Việt, 简体中文